Share card
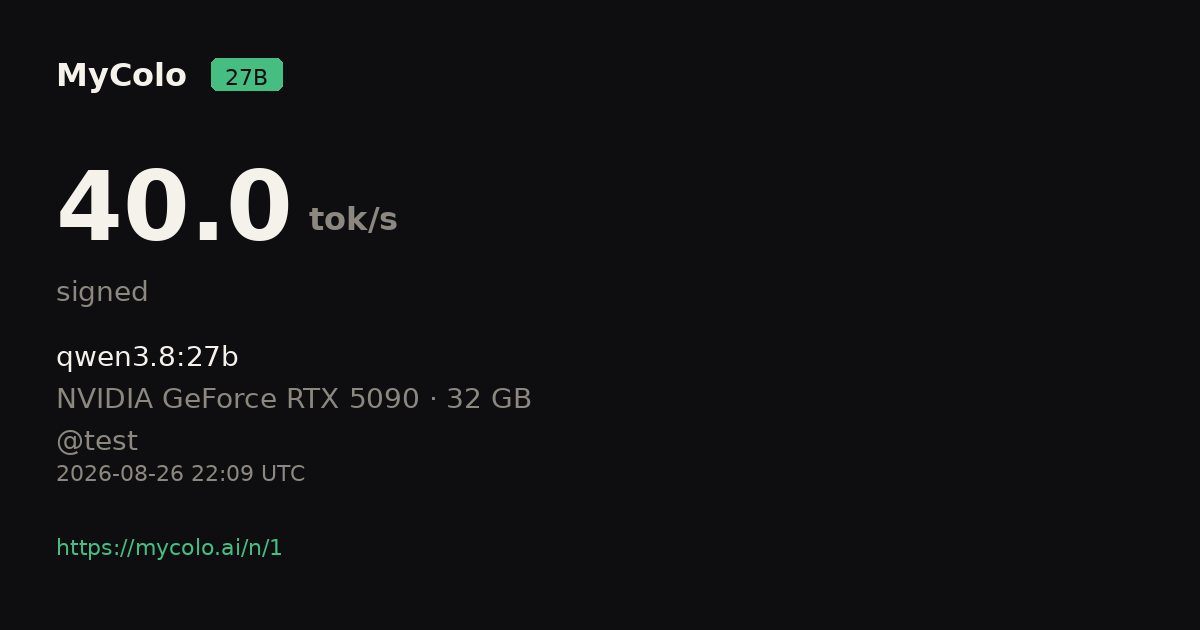
bundle 1 · measured result · 27B
40.0 tok/s
Throughput comparison
40.0 tok/s · baseline n/a · n=0
Same handle, hardware class, size track, and recipe version. Current run excluded.
Retracted — typed practice score — not a bench. Kept in the archive.
- hash
91ae010b8679cc21b48981cb372cd07d2a835581929eb406ef9f9602bb6e0303
Hardware class
{
  "driver": "580.126.18",
  "gpu_or_soc": "NVIDIA GeForce RTX 5090",
  "stack": "cuda",
  "vram_or_unified_mib": 32607
}
Sign-offs
- agent:hermes · hardware-receipt-v0